Sep 15 2026

You can’t put a human in the loop of a system that kills its agents every 3 minutes

Category: AI,AI Agent,AI Governance — disc7 @ 12:30 pm

Continuous Human Involvement Is a Fantasy. Continuous Human Authority Is an Architecture.

How to govern a fleet of hundreds of ephemeral AI agents that spawn, act, and vanish in minutes — when nobody can watch them.


Someone posed me a riddle recently, and it’s the sharpest challenge to “human-in-the-loop” orthodoxy I’ve heard in a while:

“You have a highly autonomous AI system. Hundreds of non-persistent, temporal agents are being spawned to act and then spun down within minutes. How do you plan on continuous human involvement in that scenario?”

It’s a trap — and the trap is the word continuous. Most governance frameworks, policies, and vendor decks lean on “we keep a human in the loop” as their answer to AI risk. This scenario detonates that answer. So let me answer it the way I’d answer it in a design review, not a marketing slide.

The Naive Answer Is Arithmetically Impossible

When hundreds of agents spawn and die within minutes, per-agent human review isn’t hard — it’s impossible, and you can prove it with a napkin.

Do the math: 300 agents living three minutes each is roughly 6,000 agent-lifetimes per hour. Even at a generous 30 seconds of human review a piece, you’d need dozens of reviewers working in perfect, uninterrupted parallel just to keep pace — and every one of those agents would have already acted and been spun down before any reviewer finished looking at it. The human isn’t a gate the agent waits at. They’re an archaeologist studying something that’s already gone.

So “we keep a human in the loop” isn’t a control claim for this architecture. It’s a description of a loop nobody has actually looked at.

This connects directly to a distinction I’ve written about before — the difference between human oversight (a person can step in if something looks wrong) and human control (the system can’t act until a person decides). In a fleet of ephemeral agents, naive oversight collapses into theater: a dashboard nobody can meaningfully watch at speed. The question forces us to get honest about which one we’re actually building.

The Reframe: Action vs. Authority

The correct first move is to reject the question’s hidden assumption. Continuous human action is off the table — it cannot scale to machine speed and machine scale. What remains firmly on the table is continuous human authority. Those are not the same thing, and conflating them is the entire failure mode.

Continuous involvement means a human is continuously acting. Continuous authority means human decisions are continuously in force — encoded, enforced, and un-overridable by the agents themselves — even when no human is watching any individual agent. The first is a fantasy at this scale. The second is an architecture. Here’s how you build it.

1. Move the Human Up the Abstraction Stack

Stop trying to govern each ephemeral agent. Govern the system that spawns them.

The human decision moves up a level — to the orchestration layer that mints the agents. A human approves the class of agent and its permission envelope once: what capabilities it can be granted, which tools exist in its catalog, what authority boundaries are baked into the spawn template. Every disposable instance then inherits that envelope at birth. The agents are non-persistent; the policy they’re born into is not. That inheritance is your first layer of persistent human control over non-persistent actors.

2. Compile Human Judgment Into Policy-as-Code

Since no human can watch an individual agent, the human’s judgment has to be compiled into runtime enforcement that travels with every agent.

Route every agent’s tool calls and external actions through a governed choke point — an MCP-gateway pattern — where policy-as-code evaluates each action against allow/deny rules, scope, environment, and data sensitivity at execution time. A human wrote that rule weeks ago; the rule now fires on all hundreds of agents, on every action, at machine speed. This is how oversight scales to a fleet: the human isn’t in the loop, the human’s encoded intent is. A misbehaving agent hits a wall a human built, even though no human is watching that specific agent.

3. Tier Your Actions — Autonomy Is Per-Action, Not Per-System

This is the real engineering discipline, and it’s where most programs fail. They treat the fleet as one autonomy level. It isn’t. Classify every action an agent can take by consequence and reversibility:

  • Low-consequence, reversible → fully autonomous. Run at machine speed, log everything.
  • High-consequence, reversible → autonomous, but instrumented with anomaly detection and automatic rollback triggers.
  • High-consequence, irreversible → a hard, synchronous human gate. The agent blocks and waits for a human decision, even if that breaks the “minutes” cadence.

You gate only what genuinely warrants gating — which keeps the fleet fast where speed is safe and stops it cold where it isn’t.

4. Human-On-the-Loop: Supervise the Shape, Not the Instance

Real-time human involvement in a fleet is supervisory, not participatory. Humans watch aggregate behavior — spawn rates, tool-call distributions, error and drift signals, cost and blast-radius metrics — through dashboards with circuit breakers wired in, governed by fleet-level SLOs and error budgets. When aggregate behavior crosses a threshold, the system trips automatically and pages a human with authority to act on the whole class. The human isn’t judging decision #4,712. They’re watching the shape of ten thousand decisions and holding the power to stop them.

5. The Kill-Switch Operates on the Class, Not the Instance

You can’t kill an agent that already died. So the one form of real-time human control that actually scales is the ability to instantly halt spawning, quarantine a tool from the entire fleet, or freeze the whole system. This is continuous, real-time human intervention in the only shape it can take at scale: not touching every decision, but retaining the authority and the mechanism to stop them all at once. Design the kill-switch as a first-class, tested control with unambiguous authority to pull it.

6. Ephemerality Is a Control Requirement — Mandate Traceability and Rollback

“The agent no longer exists” cannot become the new “the computer said so.” Every ephemeral agent must emit immutable, complete traces — reasoning, tool calls, inputs, outputs — to durable storage before it dies, so a human can reconstruct exactly what happened after the fact. And every consequential action needs a compensating transaction. In a fleet of the disposable, much of human control is exercised through after-action audit and reversibility, not real-time touch. The loop closes after the agent is gone — and it must actually close.

The Part Most People Won’t Say Out Loud

Everything above is how you make it work. But the honest expert answer includes a boundary. If an action is simultaneously irreversible, high-impact, and intolerant of a pre-execution human gate, that action should not be running autonomously at all. That’s not a control gap to engineer around — it’s a scoping decision to make deliberately.

The maturity isn’t “we found a clever way to keep a human continuously involved everywhere.” It’s “we drew a defensible line between what runs at machine speed and what doesn’t, and we can prove why the line sits exactly where it does.” That line is the human involvement.

Why This Is Exactly What the Regulators Are Asking

Here’s the reassuring part: this architecture isn’t a workaround for compliance — it is compliance, done properly. ISO 42001, the EU AI Act’s Article 14, and the NIST AI RMF don’t actually ask “was a human touching every decision?” They ask a sharper question: “was human authority meaningful and effective given how this system actually operates?”

For an ephemeral-agent fleet, meaningful does not equal continuous-touch. Meaningful means governed spawn templates, policy-as-code enforced on every action, synchronous gates on the irreversible few, supervisory monitoring, a class-level kill-switch, and immutable traces with rollback. A regulator — or a customer running due diligence — isn’t going to be impressed that you claimed a human was in the loop. They’re going to ask what that human could actually do, and when. This architecture answers that question. “We had oversight” does not.

The Bottom Line

You don’t achieve continuous human involvement in a system that spawns and kills hundreds of agents in minutes. You achieve continuous human authority — expressed as encoded boundaries every agent inherits, gates on the actions that warrant them, real-time power to halt the class, and after-the-fact accountability that actually closes the loop.

Continuous involvement is a fantasy at that scale. Continuous authority is an architecture. If you’re deploying autonomous or agentic AI and your governance still rests on “a human is in the loop,” the riddle above is the question your next auditor — or your next incident — is going to ask you. Better to have the architecture before they do.


DISC InfoSec helps B2B SaaS and financial-services organizations build defensible AI governance for exactly these systems — mapping where human authority actually sits in autonomous and agentic AI, and making it hold up under ISO 42001, the EU AI Act, and the NIST AI RMF. We took a virtual data room to first-audit ISO 42001 certification on M&A and financial data. If human authority can be made defensible there, it can be made defensible in your fleet.

Deploying autonomous agents? If you’re not sure your human-control model would survive an audit, it’s probably time to have that conversation—before someone else does.

📩 info@deurainfosec.com · deurainfosec.com

#AIGovernance #AgenticAI #HumanInTheLoop #AISecurity #ISO42001 #EUAIAct #NISTAIRMF #ResponsibleAI #AutonomousAI #AIRiskManagement #Cybersecurity #vCAIO #AICompliance


A note on citations: this piece reflects DISC InfoSec’s practitioner perspective and references public frameworks (ISO 42001, EU AI Act Article 14, NIST AI RMF).
Tags: AI Agents, Human in the loop


Sep 09 2026

Human Oversight vs Human Control: Where the Human Sits in AI Execution

Category: AI,AI Agent,Information Security — disc7 @ 12:07 pm

Where Does the Human Sit Relative to Execution?

Outside the loop, in it, on it, or alongside it? The position determines what evidence exists, which risk tiers are defensible, and whether Article 14 oversight is real or theatre.

Someone put a question to me recently that I thought was better than most of the governance frameworks I read: is the human positioned outside the execution process, or integrated into it at some point?

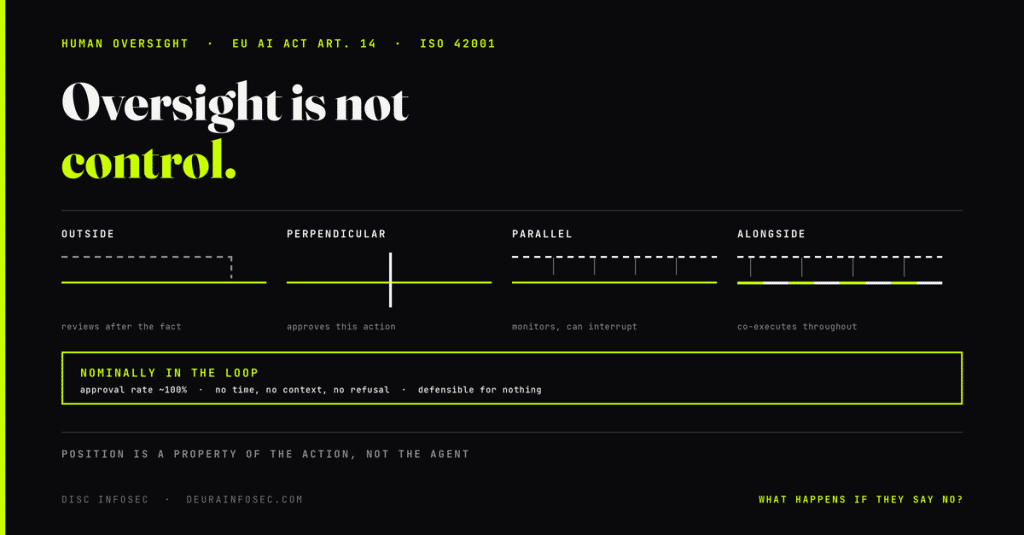
The phrasing they reached for was “perpendicular to execution,” and I want to keep that metaphor because it’s more precise than it looks. A perpendicular line crosses another at exactly one point. That is a genuinely different arrangement from running alongside, and different again from never intersecting at all. Where the human’s line meets the execution path — once, continuously, or never — determines almost everything that matters afterwards.

And it determines it in a way most organizations haven’t noticed: position determines what evidence exists. Which, as I argued in the post on ISO 42001 evidence, is the difference between having controls and being able to demonstrate control.

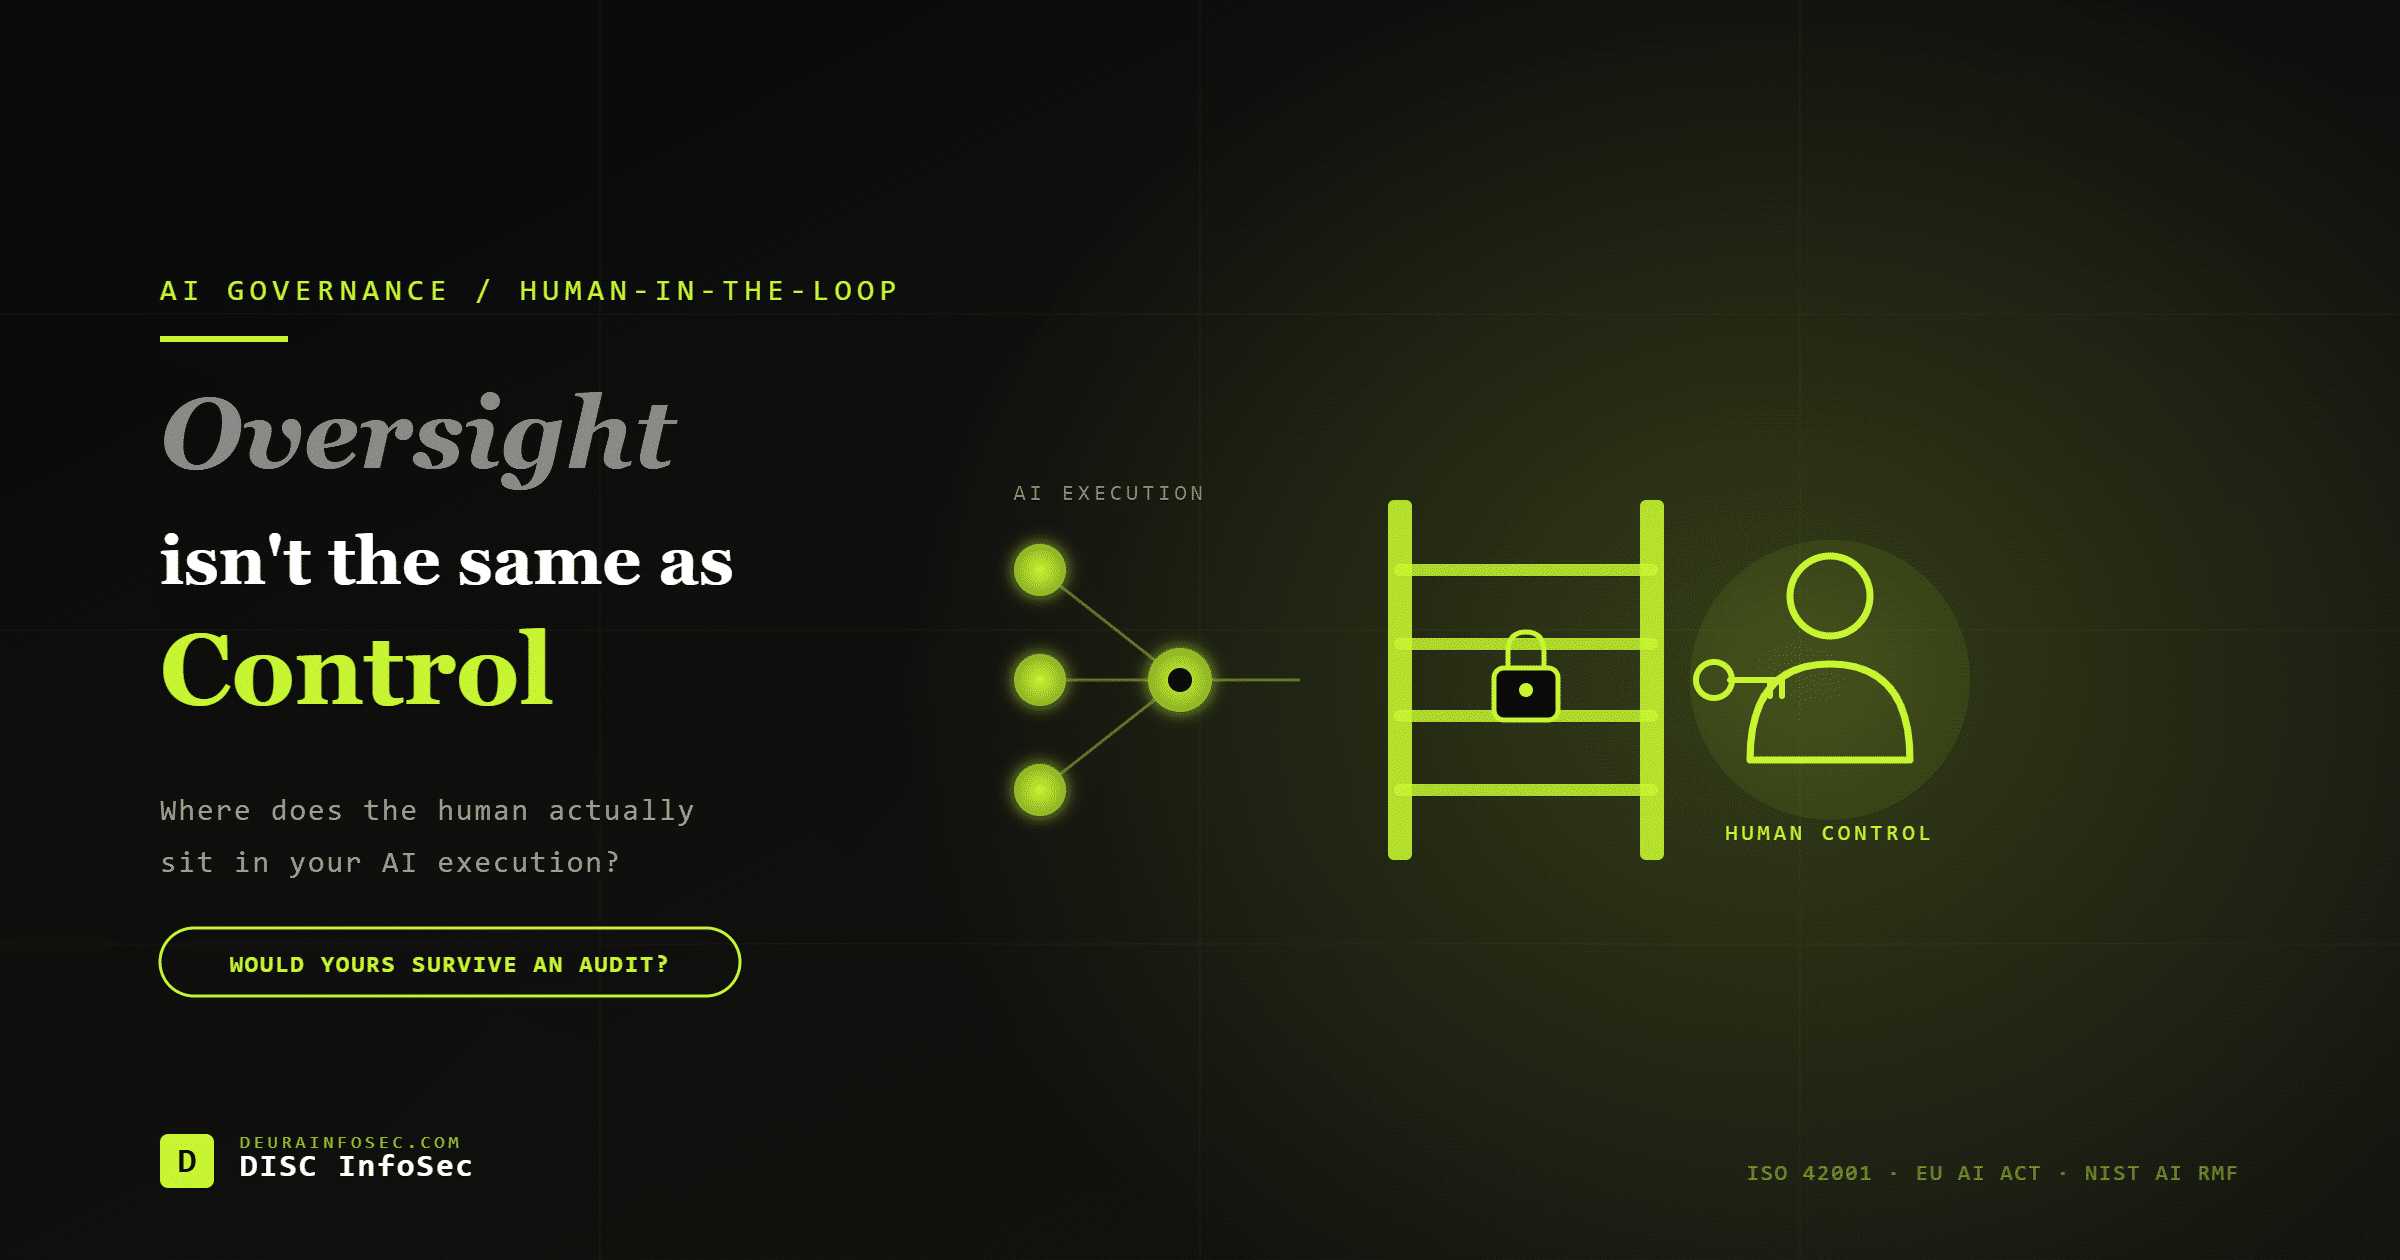
Underneath the question is the distinction that governance conversations routinely collapse: oversight is not control. Watching is not the same as being able to stop. Reviewing afterwards is not the same as authorizing beforehand. The frameworks care about the difference even when the org chart doesn’t.


Four positions, and one that pretends to be a position

PositionWhat the human actually doesLatency addedEvidence it producesDefensible for
Outside execution (post-hoc)Reviews, audits, samples after the factNoneA review record. No authorization recordTier 1 assistive work
Perpendicular (in the loop)Approves this specific action before it executesHuman-scale, per actionApproval bound to actor, tool, resource, parameters, timeTier 3–4 irreversible actions
Parallel (on the loop)Monitors live, can interrupt, doesn’t approve each actionNear-zeroMonitoring records, intervention events, tested stop capabilityTier 2–3 at volume
Alongside (co-execution)Works the task jointly, continuouslyContinuousSession records, joint attribution — often murkySkilled analytical work
Nominally in the loopClicks approve on everythingHuman-scale, wastedAn approval record that proves nothingNothing

That last row is the one to sit with, because in my experience it’s the most common arrangement in production. An approval step exists. The approval rate is effectively 100%. The human has neither the information nor the time to disagree. The organisation believes it has an in-the-loop control; what it actually has is an accountability sink — a place to assign blame, with no capacity to prevent harm.

“Oversight watches the action; control owns the gate.”

  • Oversight = a human observes what the AI/agent is doing and can intervene if something goes wrong.
  • Control = a defined decision point that determines whether an action is allowed to proceed.

For example:

AI agent wants to send $50,000 to a vendor.

Oversight: A human watches the agent execute the transaction and is supposed to stop it if necessary.

Control: The system says, “Transactions above $10,000 require human approval before execution.” The transaction cannot proceed until the gate is passed.

“Continuous collaboration during execution degrades into oversight theater at volume”

This is the most important—and controversial—part.

The argument is that if you require humans to continuously watch and collaborate with AI agents while they are executing thousands of actions, humans eventually become passive observers.

They are technically “in the loop,” but aren’t really making meaningful decisions.

That’s “oversight theater.”

The human is present, but the AI is effectively making the decisions.

“The human is present but not deciding.”

This means human presence ≠ meaningful human control.

A person clicking Approve on hundreds of AI-generated actions without understanding each decision isn’t meaningful oversight.

“Control sits perpendicular”

This is a conceptual way of saying that control should not necessarily be embedded in every moment of execution.

Instead, controls should intersect the execution process at defined decision gates:

AI/Agent → Action → CONTROL GATE → Execution

For example:

  • Low-risk action → automatically proceed
  • Medium-risk action → additional validation
  • High-risk action → human approval required
  • Prohibited action → blocked

Then:

“The gate before it ships, the audit after.”

Before execution, controls prevent unacceptable actions.

After execution, audit/evidence determines what happened, whether the control worked, and whether the system needs improvement.

Where I would challenge the statement

I wouldn’t interpret this as “humans shouldn’t collaborate continuously with AI.”

For high-risk or highly autonomous AI systems, continuous human involvement can absolutely be necessary.

The better principle is:

Don’t confuse human presence with human control.

Human presence: A person monitors a dashboard, reviews alerts, receives AI outputs, or is technically “in the loop.” Human oversight: A person can observe what the AI is doing and intervene if necessary. Human control: The person has real authority and capability to approve, reject, stop, modify, or reverse the AI’s action before or after it creates consequences.

A mature AI governance model should combine:

Preventive controls + risk-based human decision points + monitoring + post-action assurance.

That’s particularly relevant to agentic AI: the question isn’t simply “Is a human watching?” but “At which points does the human actually have authority to stop, modify, or authorize the action?”

That distinction is very close to the human-oversight issue which I’ve been exploring in my AI governance work.


Three tests for where you actually are

Your policy says where the human is supposed to sit. These tests establish where they sit.

1. The intervention test. Can the human stop the action mid-flight — not stop the next one, stop this one — and has that path been tested end to end? EU AI Act Article 14 sets the bar for high-risk systems as a demonstrated capability to intervene, interrupt, and disregard output. Note that all three verbs are active. A human who can only decline the next invocation is outside execution, whatever the diagram says. And an untested stop capability is an assumption: recent surveys put the share of organizations able to automatically terminate a misbehaving agent’s access at roughly a fifth, with a meaningful proportion of those in production never having tested the path.

2. The information test. Does the human have what they’d need in order to disagree? If the interface presents a recommendation and an approve button, the human is a signature, not a control. Real in-the-loop oversight requires the inputs, the alternatives considered, the confidence or uncertainty, and the consequence of proceeding. This is where explainability stops being an ethics topic and becomes an oversight prerequisite — a decision offered without an explanation can’t be meaningfully refused.

3. The consequence test. What happens when the human says no? If the process stops, they’re in the loop. If the request routes to someone else, gets retried until approved, or proceeds after a timeout, they’re decoration. The timeout case deserves special attention: a system that executes when approval times out has converted its human control into a delay. Fail closed, or don’t claim the control.


The problem with in-the-loop that nobody designs for

Assume you’ve built a real approval gate. There’s a decay problem, and it’s psychological rather than technical.

Humans are poor at maintaining vigilance while approving a high volume of mostly-correct outputs. The approval rate drifts toward 100% not through negligence but through calibration — if the last four hundred were fine, the four hundred and first gets less scrutiny. Add deadline pressure and the drift accelerates. This is the same pattern that gave us alert fatigue, arriving in a context where the consequence of a rubber stamp is an executed action rather than an ignored ticket.

Which produces a governance requirement most programmes miss entirely: instrument the oversight layer itself. Track approval rates over time, time-to-approval, approval bypass attempts, elevated privilege usage, and any change in approval behaviour by approver. Oversight degrades quietly — nobody files a ticket saying “I’ve started rubber-stamping” — and if you aren’t measuring the control’s effectiveness, you’ll discover its decay during an incident review.

The related design implication: don’t put humans in the loop for high-volume routine actions. It doesn’t work, it costs latency, and it manufactures false assurance. Reserve in-the-loop for the genuinely consequential, and use deterministic policy enforcement for everything else. A gate a human passes four hundred times a day is not a gate.


Matching position to risk tier

Using the tiering model from the agentic governance post — tier by maximum action impact, not typical impact:

  • Tier 1, assistive. Outside execution is appropriate. Post-hoc review, sampling, periodic audit. Nobody should be approving draft summaries.
  • Tier 2, controlled action. On the loop. Real-time monitoring, tested interrupt, automated rollback. Approval per action would be waste.
  • Tier 3, privileged autonomous. On the loop as standard, in the loop for the consequential subset. This is where the split matters: same agent, different positions depending on the action class.
  • Tier 4, high-impact or irreversible. In the loop, no exceptions, with the approval bound to the exact action and step-up authentication for the top of the range. Payment initiation, privilege changes, bulk deletion, regulated disclosure.

The important move is that position is a property of the action, not of the agent. An agent that files tickets and can also delete a production table needs both arrangements simultaneously — on the loop for the routine path, in the loop for the destructive one. Organizations that assign a single oversight posture per agent end up either strangling routine work or leaving the destructive path unguarded, and usually both.


The regulatory consequence people miss

Position isn’t only a governance choice. In two places it changes which rules apply to you.

California’s ADMT regulations. Advisory tools — systems producing recommendations, scores, or analysis for a human decision-maker — are excluded from the ADMT definition, provided there’s genuine human involvement in the final decision. CPPA staff testified during rulemaking that this narrowing reduced coverage to roughly 10% of CCPA-covered businesses. So the difference between a system that informs a human decision and one that makes it can look nearly identical in a product demo and land in entirely different regulatory buckets. But “genuine” carries the weight, and the three tests above are how a regulator will probe it. Build the advisory architecture deliberately if you’re relying on that boundary, and document the reasoning. (Not legal advice — run scoping decisions past counsel.)

EU AI Act Article 14. For high-risk systems, oversight must be a demonstrated capability, and Article 26 puts deployer obligations alongside it: competent staff, monitoring, incident notification, log retention of at least six months. Post-hoc review does not satisfy Article 14 for a high-risk system, regardless of how diligent the reviewer is. If your human sits outside execution on a high-risk system, that’s not a thin control — it’s a missing one.


The speed tension, and how it resolves

Here’s the objection to everything above, and it’s a serious one. My last two posts argued that autonomous offensive loops operate at machine speed and that human-in-the-loop defence cannot hold against them. Article 14 demands intervention capability. Machine speed demands the human step out of the execution path. Both can’t be satisfied by putting a person in front of every action.

The resolution is to change what the human does, not how fast they do it. The human moves from executing the decision to specifying and authorising the decision class in advance:

  • Define action classes with hard bounds — what may be done autonomously, to what scope, up to what magnitude, within what window.
  • Pre-authorise those classes explicitly, with a named approver and an expiry date.
  • Enforce the bounds with a deterministic policy service the model doesn’t control.
  • Route anything outside the pre-authorised envelope to a human, synchronously.
  • Preserve a tested capability to interrupt and revoke, exercised at machine speed by the policy layer and available on demand to the human.

That’s human-on-the-loop with teeth, and it satisfies both constraints because the human’s authorising act happens once, in advance, deliberately — rather than four hundred times a day under time pressure. It’s also the shape of every mature control regime we already accept: a trader has limits rather than per-trade sign-off; a surgeon has protocols rather than a supervisor approving each incision.

Which is the same principle running through everything I’ve written in this series. When I audited a client’s MCP Governance Standard and produced a v1.1 redline with 27 changes, nearly all of them reduced to one idea: authority must be bound to a specific action rather than held ambiently by a component. Pre-authorized action classes are that idea applied to human oversight. The human’s authority attaches to a defined class of action, with a boundary and an expiry, rather than floating as a general sense of being in charge.


Five design rules

  1. Assign position per action class, never per agent. One agent, several postures.
  2. Fail closed. If classification, policy lookup, approval validation, or audit logging fails, nothing executes. A timeout is not an approval.
  3. Bind the approval to the exact action — actor, tool, target resource, normalised parameters, timestamp, expiry. “Yes, send the email” is redirectable between approval and execution; “yes, send this email to this recipient” isn’t.
  4. Give the human what they’d need to refuse. Inputs, alternatives, uncertainty, consequence. An approve button with no context manufactures liability rather than control.
  5. Measure the oversight layer. Approval rates, latency, bypass attempts, behavioural drift by approver. Review it at management review, not after an incident.

What to do in the next 30 days

  1. Map every agent action class against the four positions. Write down where the human actually sits, using the three tests — not where the policy claims.
  2. Find the nominally-in-the-loop steps. Any approval running near 100% is either unnecessary or broken. Decide which, and either remove it or fix the information available to the approver.
  3. Test one intervention path end to end and record how long it took. That single artifact tells you whether your Article 14 posture is real.
  4. Check the timeout behaviour on every approval gate. If any of them proceed on timeout, that’s your most urgent fix.
  5. Instrument approval rates so the drift is visible before it matters.

The question the whole thing turns on is worth keeping in the room whenever an agent design gets discussed: not is there a human involved, but at which point does the human’s line actually cross the execution path — and what happens there if they say no?

human oversight AI execution, human in the loop vs on the loop, EU AI Act Article 14, ADMT advisory tool, automation bias, agent approval gate, ISO 42001


Work with DISC InfoSec

DISC InfoSec helps B2B SaaS and financial services organisations design human oversight that holds up to an auditor and a regulator — agent inventories and risk tiering, oversight posture per action class, approval architecture, kill-switch and intervention testing, ADMT and Article 14 scoping support, and the evidence architecture that maps to ISO/IEC 42001, NIST AI RMF, and EU AI Act Articles 14 and 26.

I led ShareVault through ISO 42001 Stage 2 certification on the first audit attempt as the internal practitioner, served as internal auditor, and authored their MCP Governance Standard.

Readiness path: free 15–20 minute readiness call → ISO 42001 gap assessment or ISO 27001 gap assessment → 7–10 day Quick-Start → full implementation and certification support.

DiscInfoSec — Principal Consultant, DISC InfoSec (Deura Information Security Consulting LLC), Petaluma, AICP, CISSP, CISM | ISO/IEC 42001 & ISO/IEC 27001 Lead Implementer | PECB Authorized Training Partner

📅 calendly.com/hd-deurainfosec 📧 info@deurainfosec.com 📞 (707) 998-5164 🌐 deurainfosec.com


References

  • Regulation (EU) 2024/1689 (EU AI Act) — Art. 14 (human oversight), Art. 26 (deployer obligations)
  • CPPA ADMT regulations under CCPA/CPRA — advisory-tool scope exclusion
  • ISO/IEC 42001:2023 — Clause 5.3 (roles), 9.1 (monitoring), 9.3 (management review); Annex A responsible-use and human-oversight controls
  • NIST AI RMF 1.0 (NIST AI 100-1) — GOVERN, MANAGE functions
  • OWASP Agentic Security Initiative; OWASP AI Agent Security Cheat Sheet
  • Kiteworks 2026 Data Security and Compliance Risk Annual Survey; Gravitee State of AI Agent Security 2026

When AI Hacks At Machine Speed, Can Humans Still Defend The Network?

Tags: AI execution, alongside the execution, Human control, Human in the loop, Human oversight, Parallel on the loop, Perpendicular in the loop